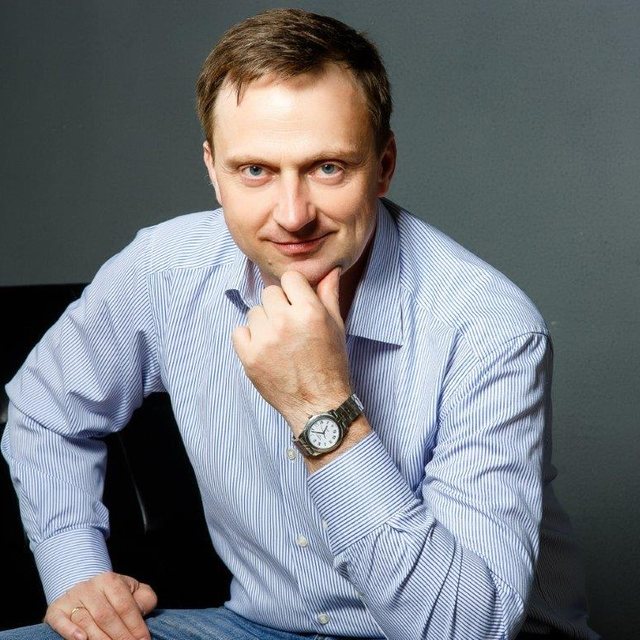
IT operations reliability consultant
Vadim Alekseev
Digital snapshots of failure causes and recipes to fix them
Who I am
20+ years building and tuning processes in operations, monitoring and support teams, and raising service availability to the target level.
- Operations system for telecom branches in the Leningrad region and Saint Petersburg (data centers, optical lines, power)
- Network monitoring and support centers, from district level up to the whole North-West - built from scratch
- Incident and problem management system in the best bank of Saint Petersburg
- Independent infrastructure audits (including work with audit and consulting firms PricewaterhouseCoopers, Accenture, KROK)
- «Master of Communications» award
What I can do
There is always enough information to say, with calculations and checks:
- where the business loses the most infrastructure resources
- which problems are most likely in the future
- what to do first for the biggest effect
- how to move operations one step up
Start simple
- No access to your systems - your existing log exports are enough
- Your team is hardly distracted: no interviews or questionnaires - the data gives most of the answers
- A fast and simple alternative to the big analytics "whales"
~50%fewer outages after transport network improvements - this is possible
18 days → 17 hoursof downtime a year: availability from 95% to 99.8%. And this is not the only example
up to ~40%of the operations budget can be redirected to more important tasks
Something to discuss?
Describe in any form what you would like to improve, and we will choose a way to work together and reach the effect you need
Details about my methods and developments:
analysis methods ·
sample report ·
operations ladder ·
services presentation