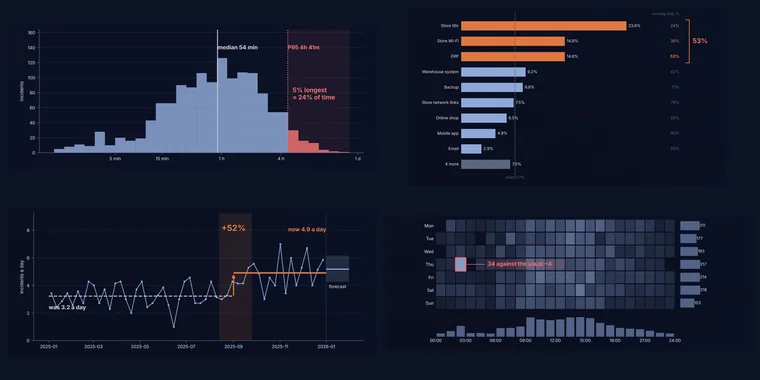
Send your incident log and we will show where downtime piles up, which failures repeat and which pull others along. We give a forecast for the next period. The first analysis is free; the result comes in one working day.
you look for the causes of failures and the best ways to fix them, and want forecasts for them.
A sample report, the operations ladder and the services deck - see them before you send your log.
12 tested methods: where downtime piles up, when and on what cycle failures happen, what has changed, which failures pull others along, and a forecast.
No interference with your infrastructure. Isolated processing, automatic masking of sensitive data.
The first analysis is free. After that everything depends on the results, your step in monitoring and automation, and your wishes.
Send an incident export - take a free full analysis, made with the key statistical models.
From "we learn about outages from the consumer" to improvements with a measured effect. Where your team actually stands, and what the next step is.
A normal company, not Google: one ordinary Tuesday hour by hour, eight signs of a mature team, and ten questions to check yourself.
Why most alerts are not worth reading, how to measure the noise, and who should be woken at night - by a written rule, not by feel.
Twelve ITIL practices ranked by what they return: kept revenue, customer trust, access to contracts, free capacity in the team.
Which problems the analysis finds most often, and what to do about each one - in ITIL / ITSM terms.
Our project was built by specialists with many years of field experience, plus the core ITIL practices. You get a useful result and/or a second opinion.
Even the first run of our engine shows the main problem groups behind 80% of downtime, and the ways to fix them.
If you keep a record of failures (time, object, event), our module will be useful to you.


A full report on a year of a retail chain's tickets, built like real life: this is how your report will look.
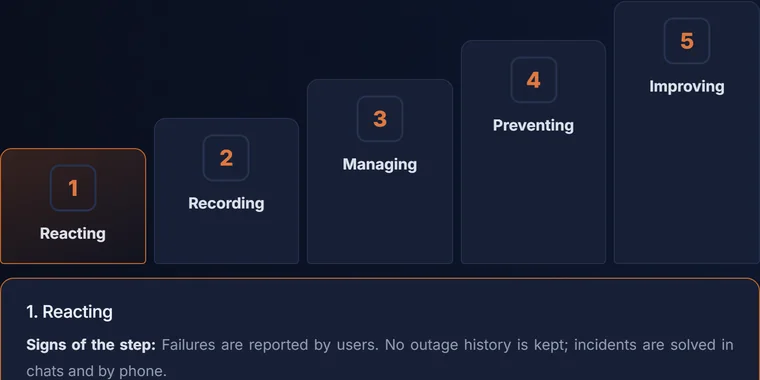
Five steps: how to recognise yourself, what hurts and what the next move is.
What we do, for whom and how: the methods with an example from the sample report.
Methods that are already tested and in use.
CSV, JSON, TXT, XLSX - up to 20 MB; a larger file - in a ZIP up to 40 MB.
Questions for a few minutes. Understand the level of the report and what to improve.
Any format will do - what you usually export (.csv .json .txt .xlsx)
Processing and checking usually take one working day.
No agents, no VPN, no server access. Only the file you decided to send.
All calculations run on our server, each file on its own. A language model writes the report text: it sees only the calculated numbers and masked names, not your log.
Your file and the report page are visible only to you, on the site, for up to 30 days.
Your data is used only for anonymized analytics, and only with your consent.
IP addresses, emails, node and object names from the log are replaced with codes before any text goes to the language model.
Run the offline script: it replaces service, host and people names with codes.
Download the script · How to run itThe founder of the project answers for the result of the analysis. The main tool: the analytics module and many years of experience in telecom and banking. Where a task needs a council of experts and more skills, other experts join.
The first analysis is free, with no strings attached. After that the price depends on how big your log is and how deep the work goes - we send an invoice by email.
We get your message, answer as fast as we can and offer you the options.
Could not send the request. Please write to hello@opslab.consulting - we will answer.